28% of my LLM budget was disappearing into thin air.
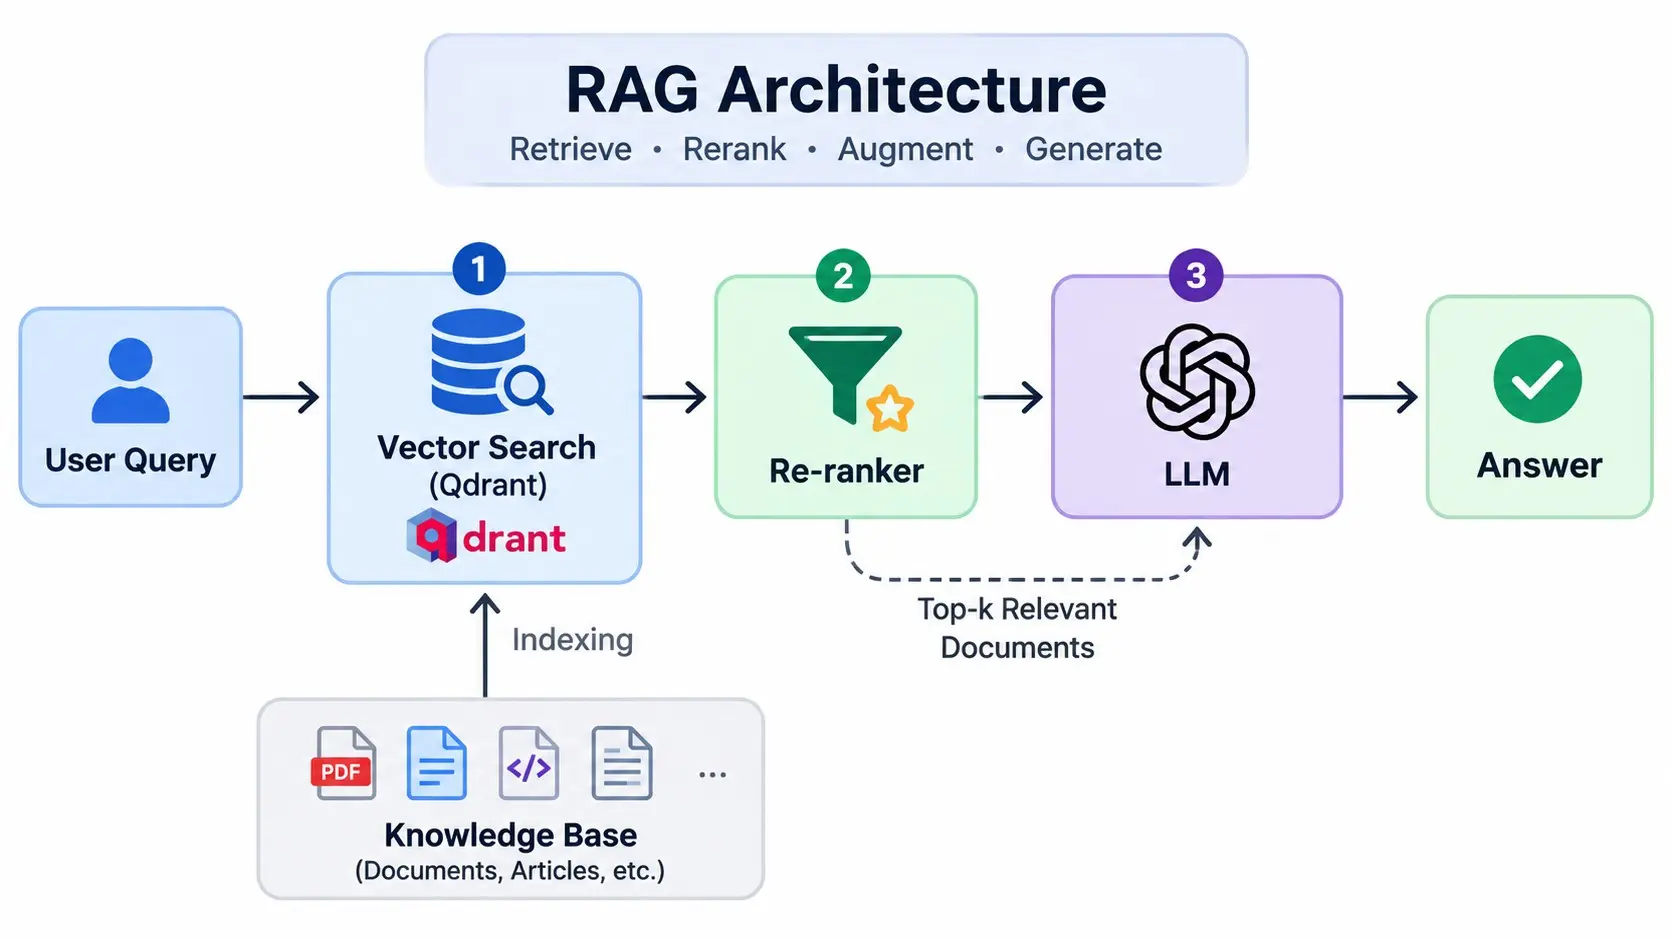
When we first built our RAG pipeline, we were sending too much raw context to OpenAI. It was slow, expensive, and the model was still getting confused. I completely rewrote the context assembly. I added a cross-encoder for re-ranking, optimized the chunking strategy, and strictly filtered what goes into the prompt. The result? Token costs dropped by 28%, retrieval latency is at 140ms, and context accuracy jumped from 68% to 94%. This is why I love AI engineering. It's not just about connecting an API. It's about making the system fast, cheap, and actually reliable for the user. I’m currently open to new opportunities. Looking for "Middle+/Senior AI or Backend roles" (fully remote, Moscow time). Stack: Python, FastAPI, LangChain, PostgreSQL, Docker. Drop me a message if your team needs someone who treats AI like real production software, not a toy.